<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" xml:lang="en"><generator uri="https://jekyllrb.com/" version="4.4.1">Jekyll</generator><link href="https://maxnoichl.eu/feed.xml" rel="self" type="application/atom+xml" /><link href="https://maxnoichl.eu/" rel="alternate" type="text/html" hreflang="en" /><updated>2026-10-08T09:49:40+00:00</updated><id>https://maxnoichl.eu/feed.xml</id><title type="html">blank</title><subtitle>I study how communities of clever people—and sometimes clever things—find their way to new ideas.
</subtitle><entry><title type="html">Overcoming the global–local trade-off in dimensionality reduction via interactivity</title><link href="https://maxnoichl.eu/blog/2026/overcoming-the-global-local-trade-off-in-dimensionality-reduction-via-interactivity/" rel="alternate" type="text/html" title="Overcoming the global–local trade-off in dimensionality reduction via interactivity" /><published>2026-10-07T10:00:00+00:00</published><updated>2026-10-07T10:00:00+00:00</updated><id>https://maxnoichl.eu/blog/2026/overcoming-the-global-local-trade-off-in-dimensionality-reduction-via-interactivity</id><content type="html" xml:base="https://maxnoichl.eu/blog/2026/overcoming-the-global-local-trade-off-in-dimensionality-reduction-via-interactivity/"><![CDATA[<p>A well-known problem in the representation of high-dimensional data is that it is very hard to find low-dimensional representations that faithfully represent both the global <em>and</em> the local structure.</p>

<p>This problem has led to the development of methods of dimensionality reduction, like <a href="https://arxiv.org/abs/2508.13747">DREAMS</a> (Kury, Kobak, and Damrich, 2026), which allow for a single explicit parameter that makes a representation focus on local or global structure.
In DREAMS, that parameter is the <a href="https://arxiv.org/html/2508.13747v2#S4.SS1">regularization strength λ</a>. At λ = 0, it produces a standard t-SNE embedding; at λ = 1, it produces a PCA embedding. We can thus optimize either for global structure, as measured by the correlation of pairwise distances in high-dimensional and low-dimensional space, or for local structure, as measured by the recall of nearest neighbors.</p>

<p>Here’s an example on Fashion-MNIST:</p>

<figure>
  <a href="/published/releases/37759233288-1/assets/img/zoommap/fashion-mnist-layouts.png" target="_blank" rel="noopener noreferrer">
    <img src="/published/releases/37759233288-1/assets/img/zoommap/fashion-mnist-layouts.png" class="img-fluid" width="1211" height="816" loading="lazy" decoding="async" alt="Six Fashion-MNIST embeddings: PCA at λ = 1, DREAMS at λ = 0.5, 0.25, 0.15, and 0.05, and t-SNE at λ = 0." />
  </a>
  <figcaption class="caption">Fashion-MNIST layouts from PCA through DREAMS to t-SNE.</figcaption>
</figure>

<p>What I’ve done here is build an interactive interface that sidesteps this trade-off by only ever showing the data at the level that’s appropriate for how far we zoom into it.</p>

<p>The interactive plots on this page are created by passing some additional JavaScript with coordinates and interpolation parameters (linear, by default) to Leland McInnes’s great <a href="https://datamapplot.readthedocs.io/en/latest/">DataMapPlot</a> library. In the DREAMS examples, the visualization starts out at λ = 1, which corresponds to PCA. As we zoom in, the coordinates of the representation shift around, leading to a viewing experience that is maybe slightly confusing, but also, at all levels, much more faithful than looking at a single-scale embedding.</p>

<p>The whole thing was pretty easy to implement with the help of Codex. I’ve made it available as <a href="https://github.com/MNoichl/zoommap">zoommap</a>, as a kind of add-on to DataMapPlot. You just compute a series of embeddings (they don’t have to be DREAMS), use zoommap to create your custom JavaScript, and pass it to DataMapPlot.</p>

<p>Here are some more examples:</p>

<p><strong>MNIST (DREAMS)</strong></p>

<figure class="zoommap-example">
  <iframe src="https://mnoichl.github.io/zoommap/artifacts/mnist_zoom.html" title="Interactive MNIST map using DREAMS layouts that change as you zoom" loading="lazy" sandbox="allow-scripts allow-downloads allow-popups allow-popups-to-escape-sandbox" allow="fullscreen" referrerpolicy="no-referrer" allowfullscreen=""></iframe>
  <figcaption class="caption">
    <a href="https://mnoichl.github.io/zoommap/artifacts/mnist_zoom.html" target="_blank" rel="noopener noreferrer">Open MNIST with DREAMS</a>.
  </figcaption>
</figure>

<p><strong>20 Newsgroups (DREAMS)</strong></p>

<figure class="zoommap-example">
  <iframe src="https://mnoichl.github.io/zoommap/artifacts/20_newsgroups_zoom.html" title="Interactive 20 Newsgroups map using DREAMS layouts that change as you zoom" loading="lazy" sandbox="allow-scripts allow-downloads allow-popups allow-popups-to-escape-sandbox" allow="fullscreen" referrerpolicy="no-referrer" allowfullscreen=""></iframe>
  <figcaption class="caption">
    <a href="https://mnoichl.github.io/zoommap/artifacts/20_newsgroups_zoom.html" target="_blank" rel="noopener noreferrer">Open 20 Newsgroups with DREAMS</a>.
  </figcaption>
</figure>

<h2 id="addendum-zooming-along-the-neighbor-embedding-spectrum">Addendum: Zooming along the neighbor embedding spectrum</h2>

<p>zoommap also works with <a href="https://github.com/sciai-lab/ne-spectrum">NE-spectrum</a>, which varies t-SNE’s attraction exaggeration ρ: stronger attraction focuses on continuous structure, approaching Laplacian eigenmaps as ρ → ∞ and giving results similar to ForceAtlas2 (ρ ≈ 30) and UMAP (ρ ≈ 4), while weaker attraction emphasizes local structure, as captured by standard t-SNE (ρ = 1) (<a href="https://jmlr.org/papers/v23/21-0055.html">Böhm, Berens, and Kobak, 2022</a>; <a href="https://doi.org/10.1101/2024.04.26.590867">Damrich et al., 2024</a>). In the examples below, zooming lowers ρ from 8 to 1.</p>

<p><strong>MNIST (NE-spectrum)</strong></p>

<figure class="zoommap-example">
  <iframe src="https://mnoichl.github.io/zoommap/ne_spectrum/artifacts/mnist_zoom.html" title="Interactive MNIST map using NE-spectrum layouts that change as you zoom" loading="lazy" sandbox="allow-scripts allow-downloads allow-popups allow-popups-to-escape-sandbox" allow="fullscreen" referrerpolicy="no-referrer" allowfullscreen=""></iframe>
  <figcaption class="caption">
    <a href="https://mnoichl.github.io/zoommap/ne_spectrum/artifacts/mnist_zoom.html" target="_blank" rel="noopener noreferrer">Open MNIST with NE-spectrum</a>.
  </figcaption>
</figure>

<p><strong>20 Newsgroups (NE-spectrum)</strong></p>

<figure class="zoommap-example">
  <iframe src="https://mnoichl.github.io/zoommap/ne_spectrum/artifacts/20_newsgroups_zoom.html" title="Interactive 20 Newsgroups map using NE-spectrum layouts that change as you zoom" loading="lazy" sandbox="allow-scripts allow-downloads allow-popups allow-popups-to-escape-sandbox" allow="fullscreen" referrerpolicy="no-referrer" allowfullscreen=""></iframe>
  <figcaption class="caption">
    <a href="https://mnoichl.github.io/zoommap/ne_spectrum/artifacts/20_newsgroups_zoom.html" target="_blank" rel="noopener noreferrer">Open 20 Newsgroups with NE-spectrum</a>.
  </figcaption>
</figure>

<p>Example notebook: <a href="https://github.com/MNoichl/zoommap/blob/main/ne_spectrum/general_example.ipynb">NE-spectrum</a>.</p>

<h2 id="references">References</h2>

<ul>
  <li>Kury, N., Kobak, D., &amp; Damrich, S. (2026). <a href="https://arxiv.org/abs/2508.13747">DREAMS: Preserving both Local and Global Structure in Dimensionality Reduction</a>. <em>Transactions on Machine Learning Research</em>.</li>
  <li>Böhm, J. N., Berens, P., &amp; Kobak, D. (2022). <a href="https://jmlr.org/papers/v23/21-0055.html">Attraction-Repulsion Spectrum in Neighbor Embeddings</a>. <em>Journal of Machine Learning Research, 23</em>(95), 1–32.</li>
  <li>Damrich, S., Klockow, M. V., Berens, P., Hamprecht, F. A., &amp; Kobak, D. (2024). <a href="https://doi.org/10.1101/2024.04.26.590867">Visualizing single-cell data with the neighbor embedding spectrum</a>. <em>bioRxiv</em> [Preprint].</li>
  <li>McInnes, L. (n.d.). <a href="https://datamapplot.readthedocs.io/en/latest/">DataMapPlot: Creating beautiful plots of data maps</a> [Software].</li>
</ul>]]></content><author><name></name></author><category term="computational-methods" /><category term="dimensionality-reduction" /><category term="visualization" /><summary type="html"><![CDATA[An interactive approach to showing global and local structure by changing a DREAMS layout as you zoom.]]></summary></entry><entry><title type="html">An Atlas of AI Tells</title><link href="https://maxnoichl.eu/blog/2026/an-atlas-of-ai-tells/" rel="alternate" type="text/html" title="An Atlas of AI Tells" /><published>2026-09-20T10:00:00+00:00</published><updated>2026-09-20T10:00:00+00:00</updated><id>https://maxnoichl.eu/blog/2026/capturing-the-ai-smell</id><content type="html" xml:base="https://maxnoichl.eu/blog/2026/an-atlas-of-ai-tells/"><![CDATA[<h2 id="what-is-this">What is this?</h2>

<p>This is a map of AI-generated texts, which are arranged and labeled according to a number of AI tells that I identified using an AI-based data-mining procedure. You can browse through the map and hover over the datapoints to see which formulations, individual words, or constructs are particularly indicative of text generated by various AI models, and familiarize yourself with the signs of AI writing.</p>

<h2 id="why-did-i-make-this">Why did I make this?</h2>

<p>It’s important for me to know whether the text I’m reading is AI-generated. As with human-authored texts, knowing the author drastically changes how I understand it and what I am willing to learn from it.</p>

<p>Luckily, tools to determine whether a text was generated with AI, like <a href="https://www.pangram.com/">Pangram</a>, or the recent open-source MELD (<a href="https://arxiv.org/abs/2605.06903">Li et al., 2026</a>) have improved quite a bit. I would not use them in scenarios in which I get sued if I’m wrong, but I think they do provide pretty good evidence of AI-generated text, even though getting around them is not impossible with some dedication. But right now, the good detectors are quite expensive or cumbersome to run, so how to decide whether to put something into them?
There are a number of lists going around outlining tells of AI writing. This project is an attempt to find a uniform process to mine such tells in an automated way and build an interface that allows people to educate themselves about them in an interactive way.</p>

<h2 id="how-are-the-ai-tells-identified">How are the AI tells identified?</h2>
<p>The whole process is inspired by this recent paper, which introduces RLIE, by <a href="https://arxiv.org/abs/2510.19698v3">Yang, Xu, Hu, and Yue (2026)</a>. The basic idea behind that paper is that you can use the capabilities and contextual information of AI models to build good text classifiers.</p>

<p>To do so, you put the AI into a loop, in which it proposes textual features that might be useful for classification. Then, another instance of the AI model grades texts according to those proposed features, and the resulting annotations are used to fit a regularized logistic regression model, which tries to predict the outcome class and weights badly performing features down.
These get then dropped, and samples of the texts on which the model performed badly get fed back to the AI model. Based on analyzing them, it proposes new features and the cycle repeats until performance stops improving.</p>

<p>For this project, I’ve adapted the process in several ways. One of them is that I’ve replaced the AI-model-based grading. Instead of coming up with rules that are then identified via an LLM, the language model immediately suggests rules that are formalized linguistic patterns or general linguistic attributes. This is inspired by the GRASP algorithm, which uses greedy search for linguistic pattern matching (<a href="https://aclanthology.org/D17-1140/">Shnarch et al., 2017</a>; <a href="https://aclanthology.org/2022.lrec-1.655/">Lertvittayakumjorn et al., 2022</a>). These rules might be quite simple, for example that a specific word or lemma appears (e.g. “genuinely”) within the text. But they can also be quite complex, e.g. having a participle-ing form and a subordinate clause introduced with “while”, alongside constraints for the right order in the sentence. This captures a while construct very common to AI writing, e.g.: “…the algorithmic moment <em>vindicates</em> Adorno’s structural claim <em>while breaking</em> his specific model in ways that matter.” (<a href="https://huggingface.co/datasets/angrygiraffe/claude-opus-4.6-4.7-reasoning-8.7k">Opus dataset</a>)</p>

<p>This rule-based approach has the advantage that it is computationally inexpensive and very fast to check the rules against the whole training set, so that the LLM doesn’t have to repeatedly “hand-label” thousands of texts. This also allows me to use a quite strong LLM, OpenAI’s Astra in high reasoning mode, for 98 calls, for the development of the underlying rules.</p>

<p>I’ve also set it up so that only positive rules for the identification of AI are admissible (the model is only detecting AI), not negative rules that are sensitive to human writing. This also changes the way the elastic logistic regression has to be fitted.</p>

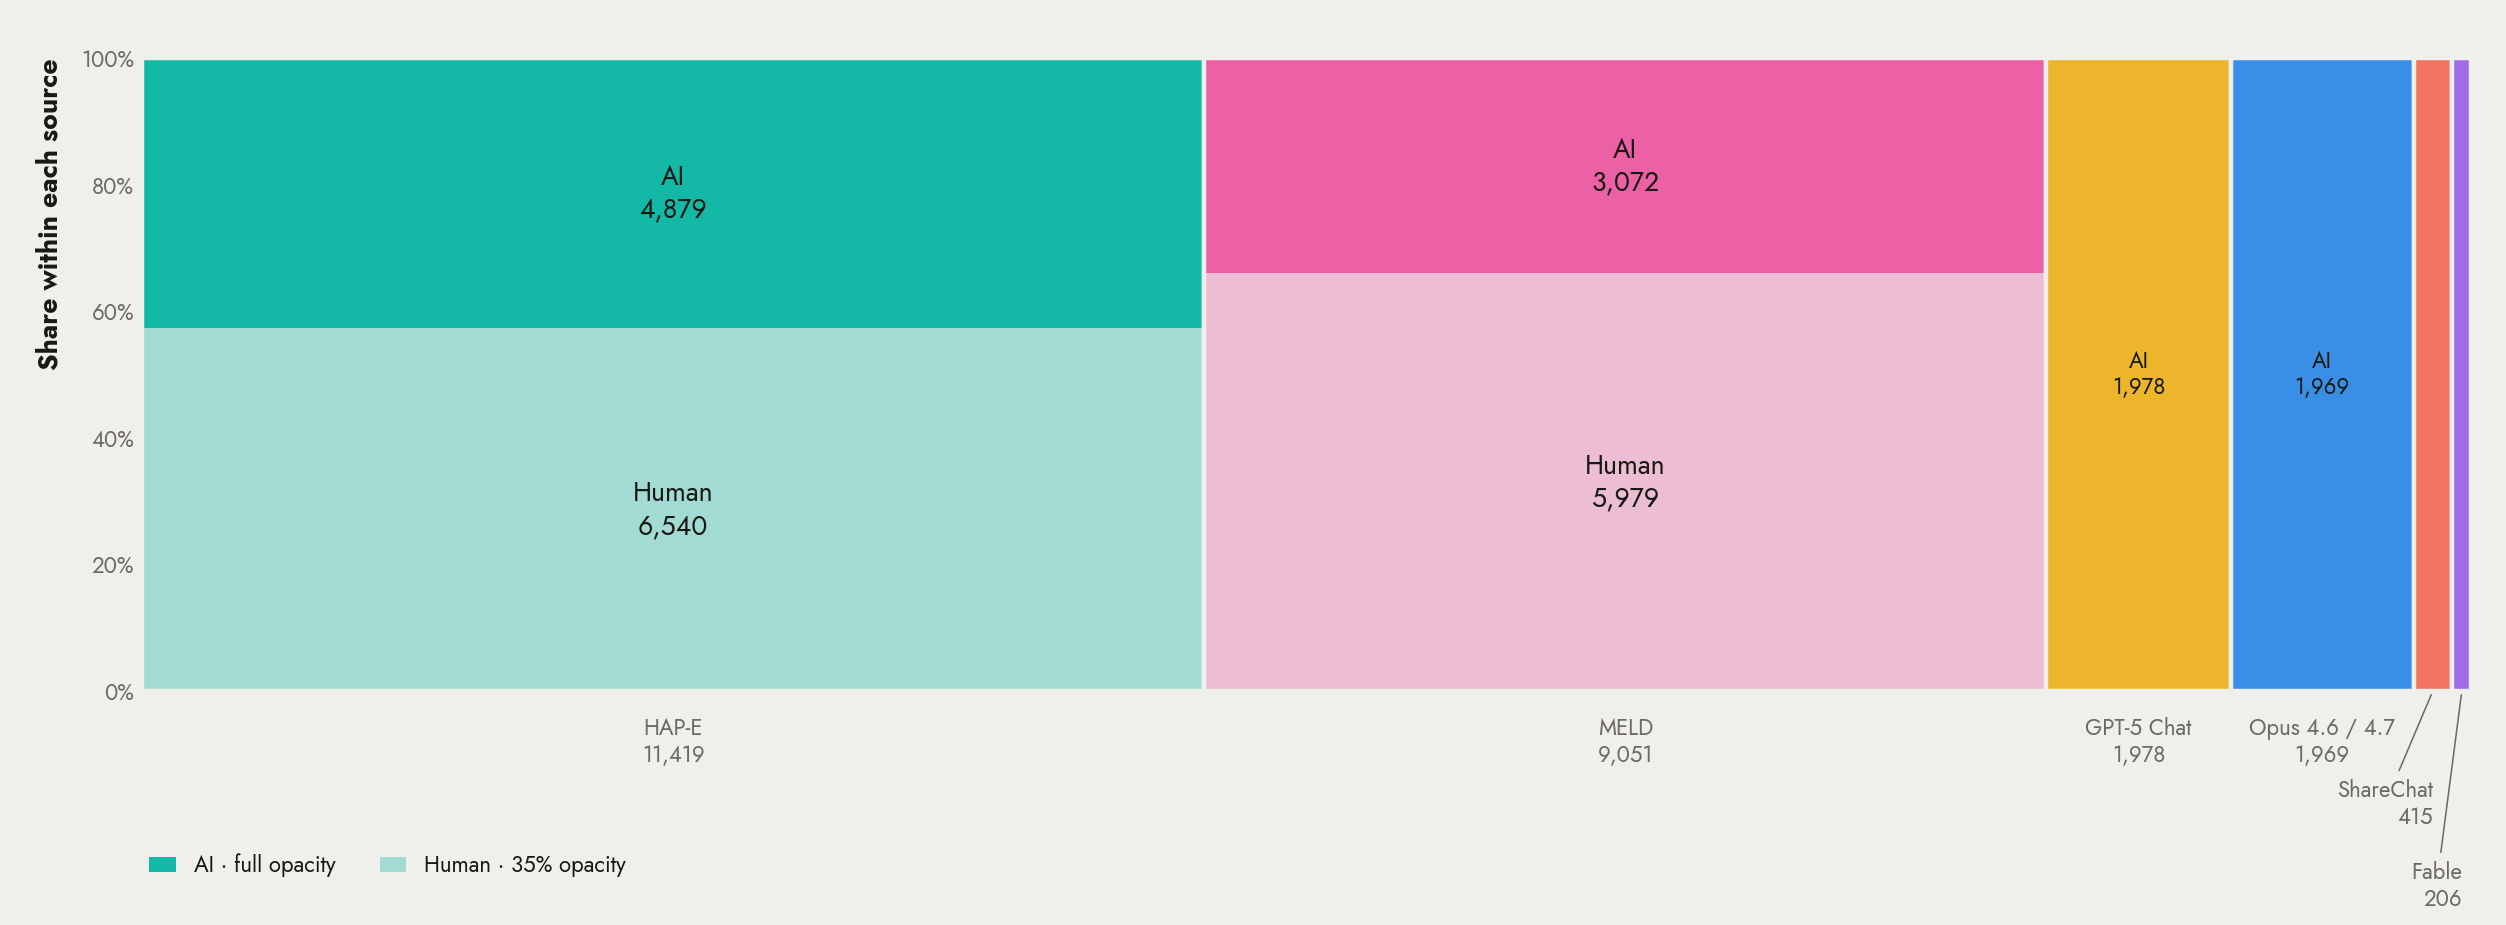
<p>The whole system is then trained on a data mix I’ve put together, which contains both human and AI writing. In particular, I have included the evaluation data from <a href="https://huggingface.co/datasets/anon-review-meld-2026/meld-eval">MELD</a>, which consists of a number of pieces of human writing that are rewritten by AI, the <a href="https://huggingface.co/datasets/browndw/human-ai-parallel-corpus">Human-AI Parallel corpus</a> (<a href="https://doi.org/10.1073/pnas.2422455122">Reinhart et al., 2025</a>), which has an LLM continue human-written text and compares it to the actual human continuation of the text, as well as a number of <a href="#datasets">smaller chat datasets</a> that I have patched together from Hugging Face that capture more recent and stronger models, including GPT-5 variants and Claude Opus, for a total of 25,038 documents (64 % train, 16 % validation, 20 % evaluation).</p>

<p>Below is a diagram of the data composition:</p>

<figure>
  <a href="/published/releases/37759233288-1/assets/img/capturing-the-ai-smell/composition_sources.png" target="_blank" rel="noopener noreferrer">
    <img src="/published/releases/37759233288-1/assets/img/capturing-the-ai-smell/composition_sources.png" class="img-fluid" width="2506" height="1228" loading="lazy" decoding="async" alt="Composition of 25,038 training and development documents. HAP-E and MELD supply most of the data, alongside smaller GPT-5 Chat, Opus, ShareChat, and Fable datasets. Column widths show source sizes; shading distinguishes AI and human text." />
  </a>
  <figcaption class="caption">Source datasets used for training and development. Click the figure to view it at full size.</figcaption>
</figure>

<p>I must note here that the classifier created by the system is very likely worse than any of the transformer-based classification AI detection systems that are currently on the market. On a held-out eval set, it reaches about 79.4% accuracy, classifying four in five documents correctly, and an AUC of 0.86, scoring an AI document above a human one 86% of the time.</p>

<p>This unreliable performance is not surprising, as it is dependent on only 100 simple rules instead of a holistic assessment of the whole text and the relationship of all kinds of words within it. This project consequently isn’t an attempt to build an AI detector, but one to come up with simple heuristics to help us become more aware of AI-generated content around us.</p>

<p>To make it easier to explore those, I split the documents into short passages, and mapped them out with <a href="https://arxiv.org/abs/1802.03426">UMAP</a> (McInnes et al., 2018) and <a href="https://datamapplot.readthedocs.io/en/latest/">DataMapPlot</a> based on the rules that were triggered by them. So you can explore the as-clauses at the top of the map, “merely”, “palpable”, “It’s not just X, it’s Y” towards the left-hand side, the em-dashes at the bottom, and “ensure” and “ensuring” on the right. You can also click on individual points to explore them in more depth, highlight only specific rules on the map, and color it by model or data source.</p>

<h2 id="what-else-have-i-tried">What else have I tried?</h2>

<p>Before settling on this RLIE-based pipeline, I tried a number of other approaches to get at these rules. First, I tried to use various AI interpretability tools on the MELD (transformer-based) classifier. I suspect this failed because the underlying transformer model seems to evaluate the text in such a heuristic way that it’s hard to decompose the effects of individual attributes of the texts out of the classifier. MELD does label individual tokens, but the individual labels don’t seem to correspond to recognizable patterns, as far as I could tell. I also tried running GRASP directly on the human/AI sample. This wasn’t successful, I think, because the greedy search of GRASP had trouble getting to more complicated rules. Finally, I tried using Monte Carlo tree search as an alternative to GRASP in the mining of rules, but found that it often leads to very repetitive rules, with only minor variations of the same rule reoccurring. Although the classification performance was comparable to the current model, the resulting rules were hard to read and didn’t seem very useful. I think the LLM-generated rules from the RLIE-inspired approach are often easier to understand because they are already generated via a process that makes sense semantically.</p>

<p><strong>Disclosure of AI use:</strong> As weekend entertainment, this project is largely coded using AI (OpenAI’s Astra model and Anthropic’s Claude Opus 5). The explanatory text was artisanally hand-typed by myself, and edited with AI (fixed typos, formatted citations, etc.).</p>

<h2 id="references">References</h2>

<ul>
  <li>Lertvittayakumjorn, P., Choshen, L., Shnarch, E., &amp; Toni, F. (2022). <a href="https://aclanthology.org/2022.lrec-1.655/">GrASP: A Library for Extracting and Exploring Human-Interpretable Textual Patterns</a>. In <em>Proceedings of the Thirteenth Language Resources and Evaluation Conference</em> (pp. 6093–6103). European Language Resources Association.</li>
  <li>Li, C., Wan, C., &amp; Paetzold, J. C. (2026). <a href="https://arxiv.org/abs/2605.06903">MELD: Multi-Task Equilibrated Learning Detector for AI-Generated Text</a>. <em>arXiv</em>, 2605.06903.</li>
  <li>McInnes, L., Healy, J., &amp; Melville, J. (2018). <a href="https://arxiv.org/abs/1802.03426">UMAP: Uniform Manifold Approximation and Projection for Dimension Reduction</a>. <em>arXiv</em>, 1802.03426.</li>
  <li>Pangram Labs. (n.d.). <a href="https://www.pangram.com/">Pangram</a> [AI-text detection service]. Accessed September 21, 2026.</li>
  <li>Reinhart, A., Markey, B., Laudenbach, M., Pantusen, K., Yurko, R., Weinberg, G., &amp; Brown, D. W. (2025). <a href="https://doi.org/10.1073/pnas.2422455122">Do LLMs write like humans? Variation in grammatical and rhetorical styles</a>. <em>Proceedings of the National Academy of Sciences, 122</em>, e2422455122.</li>
  <li>Shnarch, E., Levy, R., Raykar, V., &amp; Slonim, N. (2017). <a href="https://doi.org/10.18653/v1/D17-1140">GRASP: Rich Patterns for Argumentation Mining</a>. In <em>Proceedings of the 2017 Conference on Empirical Methods in Natural Language Processing</em> (pp. 1345–1350). Association for Computational Linguistics.</li>
  <li>Yan, Y., Nguyen, T., Su, B., Lieffers, M., &amp; Le, T. (2026). <a href="https://arxiv.org/abs/2512.17843v4">ShareChat: A Dataset of Chatbot Conversations in the Wild</a>. <em>arXiv</em>, 2512.17843, version 4.</li>
  <li>Yang, Y., Xu, H., Hu, Z., &amp; Yue, Y. (2026). <a href="https://arxiv.org/abs/2510.19698v3">RLIE: Rule Generation with Logistic Regression, Iterative Refinement, and Evaluation for Large Language Models</a>. <em>arXiv</em>, 2510.19698, version 3.</li>
</ul>

<h2 id="datasets">Datasets</h2>

<ul>
  <li><strong>HAP-E:</strong> browndw, <a href="https://huggingface.co/datasets/browndw/human-ai-parallel-corpus">Human-AI Parallel English Corpus</a>. <a href="https://huggingface.co/datasets/browndw/human-ai-parallel-corpus/tree/b514ff64988d9e322fd81c5d70d69a38e78491f5">Dataset revision</a>. See Reinhart et al. (2025).</li>
  <li><strong>MELD-eval:</strong> anon-review-meld-2026, <a href="https://huggingface.co/datasets/anon-review-meld-2026/meld-eval">MELD-eval</a>. <a href="https://huggingface.co/datasets/anon-review-meld-2026/meld-eval/tree/4c80f0fdc003854e5b6bfda90f7ac41ffb12e232">Dataset revision</a>. See Li et al. (2026).</li>
  <li><strong>GPT-5 Chat:</strong> ytz20, <a href="https://huggingface.co/datasets/ytz20/LMSYS-Chat-GPT-5-Chat-Response">LMSYS-Chat-GPT-5-Chat-Response</a>. <a href="https://huggingface.co/datasets/ytz20/LMSYS-Chat-GPT-5-Chat-Response/tree/9bc9ba920726b5a34adfb040ddc7eecafa32484b">Dataset revision</a>.</li>
  <li><strong>Opus:</strong> angrygiraffe, <a href="https://huggingface.co/datasets/angrygiraffe/claude-opus-4.6-4.7-reasoning-8.7k">claude-opus-4.6-4.7-reasoning-8.7k</a>. <a href="https://huggingface.co/datasets/angrygiraffe/claude-opus-4.6-4.7-reasoning-8.7k/tree/f0330e0ca46469b3928adef18c2b55f9476d6bd3">Dataset revision</a>.</li>
  <li><strong>ShareChat:</strong> tucnguyen, <a href="https://huggingface.co/datasets/tucnguyen/ShareChat">ShareChat</a>. <a href="https://huggingface.co/datasets/tucnguyen/ShareChat/tree/a57c741e002684939f577594fdae1559832a584d">Dataset revision</a>. See Yan et al. (2026).</li>
  <li><strong>Fable:</strong> armand0e, <a href="https://huggingface.co/datasets/armand0e/Fable-5-Chat">Fable-5-Chat</a>. <a href="https://huggingface.co/datasets/armand0e/Fable-5-Chat/tree/38cf282edea1eac301321b04a1961d326c32293c">Dataset revision</a>.</li>
</ul>

<!-- You can return to the explorer by scrolling up, or
[open it in a separate tab](/published/releases/37759233288-1/assets/html/ai-rule-explorer.html)
to keep it beside the article while reading. -->]]></content><author><name></name></author><category term="ai" /><category term="language" /><summary type="html"><![CDATA[An interactive exploration of patterns in AI-generated and human-written passages.]]></summary></entry><entry><title type="html">Patterns, Pathways &amp;amp; Surprises</title><link href="https://maxnoichl.eu/blog/2025/epsa-poster/" rel="alternate" type="text/html" title="Patterns, Pathways &amp;amp; Surprises" /><published>2025-08-29T12:00:00+00:00</published><updated>2025-08-29T12:00:00+00:00</updated><id>https://maxnoichl.eu/blog/2025/epsa-poster</id><content type="html" xml:base="https://maxnoichl.eu/blog/2025/epsa-poster/"><![CDATA[<p>Here’s the poster I presented at the European Philosophy of Science Association’s conference in Groningen this year. It introduces <a href="https://huggingface.co/spaces/MaxNoichl/openalex_mapper">OpenAlex Mapper</a>, an interactive, online, science-mapping platform I’ve built.</p>

<style>
  .poster-preview {
    margin: 0 auto 1.5rem;
    max-width: 720px;
  }

  .poster-preview a {
    display: block;
  }

  .poster-preview-note {
    margin: 0.75rem 0 1.5rem;
    text-align: center;
  }

  .pdf-container {
    width: 100%;
    height: 1200px;
  }

  .poster-pdf {
    display: block;
    width: 100%;
    height: 100%;
  }

@media (max-width: 768px) {
  .poster-preview {
    margin-bottom: 1rem;
  }

  .pdf-container {
    height: 70vh;
    min-height: 420px;
  }
}
</style>

<div class="poster-preview">
  <a href="/published/releases/37759233288-1/assets/img/epsa2025/Poster_EPSA_final_MN_small.pdf" target="_blank" rel="noopener noreferrer">


<figure>
  <picture>
    <!-- Auto scaling with imagemagick -->
    <!--
      See https://www.debugbear.com/blog/responsive-images#w-descriptors-and-the-sizes-attribute and
      https://developer.mozilla.org/en-US/docs/Learn/HTML/Multimedia_and_embedding/Responsive_images for info on defining 'sizes' for responsive images
    -->
    
      <source class="responsive-img-srcset" srcset="/published/releases/37759233288-1/assets/img/epsa2025/poster_full_preview-480.webp 480w,/published/releases/37759233288-1/assets/img/epsa2025/poster_full_preview-800.webp 800w,/published/releases/37759233288-1/assets/img/epsa2025/poster_full_preview-1400.webp 1400w," sizes="95vw" type="image/webp" />
    
    <img src="/published/releases/37759233288-1/assets/img/epsa2025/poster_full_preview.jpg" class="img-fluid rounded z-depth-1" width="100%" height="auto" alt="Full preview of the EPSA 2025 poster Patterns, Pathways &amp; Surprises" loading="eager" onerror="this.onerror=null; $('.responsive-img-srcset').remove();" />
  </picture>

  
</figure>

  </a>
</div>

<p class="poster-preview-note">
  On phones, it may be easier to
  <a href="/published/releases/37759233288-1/assets/img/epsa2025/Poster_EPSA_final_MN_small.pdf" target="_blank" rel="noopener noreferrer">open the poster PDF directly</a>.
</p>

<div class="pdf-container">
<object class="poster-pdf" data="/published/releases/37759233288-1/assets/img/epsa2025/Poster_EPSA_final_MN_small.pdf#view=FitH" type="application/pdf">
<embed class="poster-pdf" src="/published/releases/37759233288-1/assets/img/epsa2025/Poster_EPSA_final_MN_small.pdf" type="application/pdf" />
<p>Your device may not display embedded PDFs. <a href="/published/releases/37759233288-1/assets/img/epsa2025/Poster_EPSA_final_MN_small.pdf">Tap here to open or download the poster.</a></p>
</object>
</div>]]></content><author><name></name></author><category term="poster" /><category term="openalex" /><category term="philosophy" /><category term="ai" /><category term="sciencemapping" /><summary type="html"><![CDATA[Our poster for EPSA 2025, introducing OpenAlex mapper]]></summary></entry><entry><title type="html">GAP-Workshop – Data-Driven Methods for Philosophy</title><link href="https://maxnoichl.eu/blog/2025/gap_workshop_comp_methods/" rel="alternate" type="text/html" title="GAP-Workshop – Data-Driven Methods for Philosophy" /><published>2025-06-09T12:00:00+00:00</published><updated>2025-06-09T12:00:00+00:00</updated><id>https://maxnoichl.eu/blog/2025/gap_workshop_comp_methods</id><content type="html" xml:base="https://maxnoichl.eu/blog/2025/gap_workshop_comp_methods/"><![CDATA[<div class="row mt-3 justify-content-center">
  <div class="col-12">


<figure>
  <picture>
    <!-- Auto scaling with imagemagick -->
    <!--
      See https://www.debugbear.com/blog/responsive-images#w-descriptors-and-the-sizes-attribute and
      https://developer.mozilla.org/en-US/docs/Learn/HTML/Multimedia_and_embedding/Responsive_images for info on defining 'sizes' for responsive images
    -->
    
      <source class="responsive-img-srcset" srcset="/published/releases/37759233288-1/assets/img/gap/klee_cut-480.webp 480w,/published/releases/37759233288-1/assets/img/gap/klee_cut-800.webp 800w,/published/releases/37759233288-1/assets/img/gap/klee_cut-1400.webp 1400w," sizes="95vw" type="image/webp" />
    
    <img src="/published/releases/37759233288-1/assets/img/gap/klee_cut.jpg" width="100%" height="auto" loading="eager" onerror="this.onerror=null; $('.responsive-img-srcset').remove();" />
  </picture>

  
</figure>

  </div>
</div>

<p><br /></p>

<p><a href="https://gap12.de/index.html">Satellite workshop</a> at the conference of the <em>Gesellschaft für Analytische Philosophie</em> (GAP), 12–13 September, Düsseldorf.</p>

<p><strong>Location:</strong> Room 23.21 U1.72, Heinrich Heine University Düsseldorf.</p>

<p><strong>Additional information:</strong> <a href="https://mnoichl.github.io/data-driven-philosophy-GAP2025/#/section-1">https://mnoichl.github.io/data-driven-philosophy-GAP2025/#/section-1</a></p>

<p><strong>Update 2:</strong> The talks of Catherine Herfeld and Adrian Wüthrich have been switched. The change is reflected in the updated programme below.</p>

<p><strong>Update:</strong> In this workshop we will rely on Google Colab notebooks. This service is free but requires a Google account, which you can set up in advance. If you already use Google Drive or have a Gmail account, you are all set. If you want to participate without registering for a Google account, you can also use a local Python installation on your own computer. It’s great if you can set this up beforehand, but if you don’t find time for it, we can also figure it out during the workshop.</p>

<p><em>Organization: <a href="https://gregorboes.com/">Gregor Bös</a> and <a href="https://www.maxnoichl.eu">Max Noichl</a></em></p>

<p>Computational methods have revolutionized most fields of academic research, including the humanities. More recently, they have also been put to use in the philosophy of science, history of philosophy, and metaphilosophy. In this satellite workshop, we discuss techniques from the digital humanities, network science, and artificial intelligence that can support the study of philosophical corpora.</p>

<p>The workshop comprises keynote lectures by Prof. <a href="https://catherineherfeld.weebly.com/">Catherine Herfeld</a> and Prof. <a href="https://www.tu.berlin/hps-mod-sci/ueber-uns/team/prof-dr-adrian-wuethrich">Adrian Wüthrich</a> that showcase computational methods in philosophical research. After these showcases, Gregor Bös and Max Noichl will assist the participants in developing their own initial research questions that make use of digital methods and explore first implementations. The organizers have prepared templates to support participants without programming experience or who have not yet used computational methods in their research. More experienced participants can use the sessions to exchange ideas and develop their own projects, presenting the state of their progress in the concluding session.</p>

<p>If participants already have project ideas when signing up, we encourage them to get in contact with the organizers to discuss potential data sources and methods. Participants are also very welcome to sign up to continue working on existing digital projects and to contribute to the exchange of approaches.</p>

<p>Duration: 1 ½ days</p>

<p>Expected number of participants: 15–25</p>

<h2 id="tentative-schedule">Tentative Schedule</h2>

<p><em>Day 1</em><br /></p>

<p><b class="small-caps">09:00 – 09:30</b>: Arrival and coffee.<br />
<b class="small-caps">09:30 – 10:00</b>: Introductions and general remarks.<br />
<b class="small-caps">10:00 – 10:45</b>: Keynote by Adrian Wüthrich.<br />
<b class="small-caps">10:45 – 11:15</b>: Discussion of Adrian Wüthrich’s keynote.<br />
<b class="small-caps">11:15 – 11:30</b>: <em>Short break</em><br />
<b class="small-caps">11:30 – 12:00</b>: Presentation on network visualization in <a href="https://edhiphy.org/">edhiphy</a> by Gregor Bös.<br />
<b class="small-caps">12:00 – 13:30</b>: <em>Lunch break</em><br />
<b class="small-caps">13:30 – 14:15</b>: Keynote by Catherine Herfeld.<br />
<b class="small-caps">14:15 – 14:45</b>: Discussion of Catherine Herfeld’s keynote.<br />
<b class="small-caps">14:45 – 15:00</b>: <em>Short break</em><br /><br />
<b class="small-caps">15:00 – 15:30</b>: Presentation on <a href="https://huggingface.co/spaces/m7n/openalex_mapper">OpenAlex Mapper</a> by Max Noichl.<br />
<b class="small-caps">15:30 – 17:00</b>: Guided walkthrough of state-of-the-art text-analysis notebooks (different difficulties available).<br />
<b class="small-caps">17:00 – 18:00</b>: Brainstorming session, initiating individual and/or group projects.<br />
<br /></p>

<p><em>Day 2</em><br /></p>

<p><b class="small-caps">09:00 – 09:30</b>: Arrival and coffee.<br />
<b class="small-caps">09:30 – 12:00</b>: Facilitated project work.<br />
<b class="small-caps">12:00 – 13:00</b>: <em>Lunch break</em> <br />
<b class="small-caps">13:00 – 14:00</b>: Continued project work.<br />
<b class="small-caps">14:00 – 15:00</b>: Project snapshots and farewell.<br /></p>]]></content><author><name></name></author><category term="philosophy" /><category term="philosophy" /><category term="computational-methods" /><category term="digital-humanities" /><category term="ai" /><summary type="html"><![CDATA[GAP-Satellite workshop]]></summary></entry><entry><title type="html">On alphabetical authorship order in philosophy</title><link href="https://maxnoichl.eu/blog/2025/alphabetization_in_philosophy/" rel="alternate" type="text/html" title="On alphabetical authorship order in philosophy" /><published>2025-06-01T12:00:00+00:00</published><updated>2025-06-01T12:00:00+00:00</updated><id>https://maxnoichl.eu/blog/2025/alphabetization_in_philosophy</id><content type="html" xml:base="https://maxnoichl.eu/blog/2025/alphabetization_in_philosophy/"><![CDATA[<p>I have recently been thinking about alphabetical authorship norms in philosophy. On those rather rare occasions when philosophers co-author a paper, they must decide whether to list authors alphabetically by surname or to apply another ordering convention. The most common alternatives include ordering by individual contribution, by responsibility for funding acquisition, by coin toss, and so on.</p>

<p>Knowing the prevailing norm for authorship order matters, because this norm likely shapes how work is perceived. For example, if you and your co-authors decide to list names alphabetically in an environment where most people rank them by contribution, casual readers might assume that a later-alphabet colleague pulled less weight than they actually did. On the other hand, if you ordered by contribution but the resulting list happened to be alphabetical in a field that already leans toward alphabetization, that deliberate choice might be obscured.</p>

<h2 id="data">Data</h2>
<p>Through a project I am working on with Hein Duijf, I have a large dataset of philosophical literature lying around that will allow us to track this. The dataset was created by using the <a href="https://philpapers.org/journals">PhilPapers list of philosophy journals</a>, which contains more than a thousand titles, and extracting their corresponding bibliometric data from <a href="https://openalex.org">OpenAlex</a>, resulting in a collection of 1.4 million articles. This dataset is very expansive because PhilPapers adopts a rather liberal approach to classifying journals as philosophy journals. For our purposes, this is beneficial, as co-authored work is likely to occur more frequently at disciplinary borders, where scholars engage in interdisciplinary collaborations.</p>

<p>We can quickly assess how common co-authorship is in philosophy by examining the length of author lists. Figure 1 shows that the vast majority of philosophical articles are single-authored, with a small minority of zero-author contributions. These largely reflect institutionally authored items (letters from editors, published bibliographies, or lists of books received). After filtering out the most egregious entries by manually reviewing the fifty journals with the highest article counts and removing any that clearly fell outside philosophy, our final sample comprises 169,415 articles with more than one author.</p>

<p>All code for this project is available on <a href="https://github.com/MNoichl/philo_alphabet"> GitHub</a>, which also includes the complete list of excluded journals.</p>

<div class="row mt-3 justify-content-center">
  <div class="col-12">


<figure>
  <picture>
    <!-- Auto scaling with imagemagick -->
    <!--
      See https://www.debugbear.com/blog/responsive-images#w-descriptors-and-the-sizes-attribute and
      https://developer.mozilla.org/en-US/docs/Learn/HTML/Multimedia_and_embedding/Responsive_images for info on defining 'sizes' for responsive images
    -->
    
      <source class="responsive-img-srcset" srcset="/published/releases/37759233288-1/assets/img/authorship_order_philosophy/coauthorship_distribution-480.webp 480w,/published/releases/37759233288-1/assets/img/authorship_order_philosophy/coauthorship_distribution-800.webp 800w,/published/releases/37759233288-1/assets/img/authorship_order_philosophy/coauthorship_distribution-1400.webp 1400w," sizes="95vw" type="image/webp" />
    
    <img src="/published/releases/37759233288-1/assets/img/authorship_order_philosophy/coauthorship_distribution.png" width="100%" height="auto" loading="eager" onerror="this.onerror=null; $('.responsive-img-srcset').remove();" />
  </picture>

  
    <figcaption class="caption">Figure 1. Distribution of author counts in philosophical articles.</figcaption>
  
</figure>

  </div>
</div>

<p><br /></p>

<h2 id="measuring-intentional-alphabetization">Measuring intentional alphabetization</h2>

<p>Now, how do we measure the alphabetization rate in philosophy? It’s more involved than simply counting the papers whose author lists appear in alphabetical order, because other conventions, like randomizing author order or ranking authors by contribution, can also yield alphabetical sequences by accident. We therefore need to adjust the raw alphabetization count by the level of alphabetization expected under chance alone.</p>

<p>Following <a href="https://arxiv.org/pdf/1206.4863">Waltman (2012)</a>, I compute an intentional-alphabetization score for each paper as</p>

\[s = \frac{A - p}{1 - p}\]

<p>where \(A=1\) if the published author list is alphabetical and \(A=0\) otherwise, while \(p\) is the probability that the same set of names would appear in alphabetical order by pure chance.
Averaging s over all papers in a field yields a field-level index that ranges from 0 to +1, with values near +1 denoting a strong, or total alphabetical norm and values near 0 its absence.</p>

<p>I diverge from Waltman’s analytic approach for \(p\): instead of using the closed-form \(1/n!\) (with \(n\) the number of authors), I estimate \(p\) by repeatedly shuffling each paper’s author list programmatically and recording how often the permutation is alphabetical. This Monte-Carlo procedure introduces negligible extra noise but gracefully handles edge cases such as repeated surnames, which are common among relatives co-authoring and many Asian names.</p>

<div class="row mt-3 justify-content-center">
  <div class="col-12">


<figure>
  <picture>
    <!-- Auto scaling with imagemagick -->
    <!--
      See https://www.debugbear.com/blog/responsive-images#w-descriptors-and-the-sizes-attribute and
      https://developer.mozilla.org/en-US/docs/Learn/HTML/Multimedia_and_embedding/Responsive_images for info on defining 'sizes' for responsive images
    -->
    
      <source class="responsive-img-srcset" srcset="/published/releases/37759233288-1/assets/img/authorship_order_philosophy/coauthorship_order_over_time-480.webp 480w,/published/releases/37759233288-1/assets/img/authorship_order_philosophy/coauthorship_order_over_time-800.webp 800w,/published/releases/37759233288-1/assets/img/authorship_order_philosophy/coauthorship_order_over_time-1400.webp 1400w," sizes="95vw" type="image/webp" />
    
    <img src="/published/releases/37759233288-1/assets/img/authorship_order_philosophy/coauthorship_order_over_time.png" width="100%" height="auto" loading="eager" onerror="this.onerror=null; $('.responsive-img-srcset').remove();" />
  </picture>

  
    <figcaption class="caption">Figure 2. Intentional alphabetization rate in multi-authored philosophy articles over time.</figcaption>
  
</figure>

  </div>
</div>

<p><br /></p>

<p>Figure 2 traces these values over time. A little less than half of the multi-authored articles in our sample appear in alphabetical order. Remembering that most collaborations in philosophy are by two people, we can assume that a good part of these can plausibly be chalked up to chance. The share of deliberately alphabetical ordering (or alphabetization index) is much lower, peaking at about 20 percent in the aughts and drifting down into the 10–15 percent range in recent years. Taken together, these numbers indicate that <em>philosophy lacks a robust convention of alphabetical co-authorship</em>, and that the little intentional alphabetical ordering that once existed has been shrinking.</p>

<h2 id="comparing-journals">Comparing Journals</h2>

<p>How do these results look when we compare different journals? For a first look, I took the list of top journals proposed by <a href="https://link.springer.com/article/10.1007/s11229-023-04342-9">De Bruin (2023)</a>. The resulting average intentional-alphabetization values, together with bootstrapped confidence intervals are shown in Figure 3. For my own interest, I also included two philosophy-of-science journals. Note that <em>Ergo</em> is absent from the dataset and the <em>Proceedings of the Aristotelian Society</em> is excluded because the dataset contained only two co-authored papers. As I am mostly interested here in contemporary conventions, I also included only papers from the last fifteen years.</p>

<div class="row mt-3 justify-content-center">
  <div class="col-12">


<figure>
  <picture>
    <!-- Auto scaling with imagemagick -->
    <!--
      See https://www.debugbear.com/blog/responsive-images#w-descriptors-and-the-sizes-attribute and
      https://developer.mozilla.org/en-US/docs/Learn/HTML/Multimedia_and_embedding/Responsive_images for info on defining 'sizes' for responsive images
    -->
    
      <source class="responsive-img-srcset" srcset="/published/releases/37759233288-1/assets/img/authorship_order_philosophy/alphabetical_order_top_journals-480.webp 480w,/published/releases/37759233288-1/assets/img/authorship_order_philosophy/alphabetical_order_top_journals-800.webp 800w,/published/releases/37759233288-1/assets/img/authorship_order_philosophy/alphabetical_order_top_journals-1400.webp 1400w," sizes="95vw" type="image/webp" />
    
    <img src="/published/releases/37759233288-1/assets/img/authorship_order_philosophy/alphabetical_order_top_journals.png" width="100%" height="auto" loading="eager" onerror="this.onerror=null; $('.responsive-img-srcset').remove();" />
  </picture>

  
    <figcaption class="caption">Figure 3. Intentional alphabetization rate in top philosophy journals.</figcaption>
  
</figure>

  </div>
</div>

<p><br /></p>

<p>We note considerable variation in intentional alphabetical ordering among philosophy journals. The highest level of intentional alphabetization is found in the <em>Journal of Philosophy</em> with around 60%. The average intentional alphabetization rate among all of these journals is roughly 40%.</p>

<p>This aligns with the 38.8% Waltman reports for the Web of Science “Philosophy” category for the years 2007–2011. The value is far lower than that for mathematics (73.3%), finance (68.3%) and particle physics (56.7%), but noticeably higher than those typical of other humanities like history (29.9%) or linguistics (15.6%). It is also considerably higher than the global average we found in our data shown in Figure 2. While it seems like Waltman appears to have observed alphabetical ordering in philosophy essentially at its peak with his sample, there is still a roughly 18 percentage point difference. I couldn’t reconstruct Waltman’s sample, as I don’t have access to what the <em>Web of Science category</em> of philosophy contained thirteen years ago, but I suspect that it took a relatively narrow view of philosophy. E.g., it separates out history and philosophy of science as a separate category (18.5%).</p>

<p>To investigate which sorts of journals shift the average up or down in our sample (and therefore might explain this discrepancy), I extracted those with the highest and lowest alphabetization values over the past fifteen years. The plot displays only journals with more than 100 data points. I also removed every journal whose mean alphabetization value falls below zero; such a negative score signals that the papers in the journal systematically resist alphabetical authorship ordering. Closer inspection suggests that this pattern usually arises because a single person appears as co-author on many, or most, of the articles. This could be an intentional and somewhat worrisome editorial practice, or merely a coding error in how editors were recorded in the database.</p>

<div class="row mt-3 justify-content-center">
  <div class="col-12">


<figure>
  <picture>
    <!-- Auto scaling with imagemagick -->
    <!--
      See https://www.debugbear.com/blog/responsive-images#w-descriptors-and-the-sizes-attribute and
      https://developer.mozilla.org/en-US/docs/Learn/HTML/Multimedia_and_embedding/Responsive_images for info on defining 'sizes' for responsive images
    -->
    
      <source class="responsive-img-srcset" srcset="/published/releases/37759233288-1/assets/img/authorship_order_philosophy/alphabetical_order_by_journal_top_bottom-480.webp 480w,/published/releases/37759233288-1/assets/img/authorship_order_philosophy/alphabetical_order_by_journal_top_bottom-800.webp 800w,/published/releases/37759233288-1/assets/img/authorship_order_philosophy/alphabetical_order_by_journal_top_bottom-1400.webp 1400w," sizes="95vw" type="image/webp" />
    
    <img src="/published/releases/37759233288-1/assets/img/authorship_order_philosophy/alphabetical_order_by_journal_top_bottom.png" width="100%" height="auto" loading="eager" onerror="this.onerror=null; $('.responsive-img-srcset').remove();" />
  </picture>

  
    <figcaption class="caption">Figure 4. The journals in our sample with the highest and lowest intentional alphabetization-rates.</figcaption>
  
</figure>

  </div>
</div>

<p><br /></p>

<p>We see that the highest-scoring journals are basically logic and mathematics-venues, (and <em>Ethics</em> for reasons that I couldn’t determine.) so it is no surprise that they follow alphabetical conventions. Several other leading philosophy journals end up in the 40%–60% range of intentional alphabetical authorship ordering. At the bottom sit journals with almost no deliberate alphabetical ordering. Here we see a lot of medicine and nursing ethics, as well as a number of non-English journals. I also suspect that less analytical outlets tend towards less alphabetical ordering. Overall, I suspect that both the highest and lowest amounts of alphabetical ordering in our sample of philosophy are imported from the bordering disciplines in which philosophers author as well.</p>

<h2 id="rankings-vs-the-alphabet">Rankings vs. the alphabet</h2>

<p>While reviewing the original journal ranking, it appeared to me that the more prominent journals seemed likelier to adopt alphabetical authorship. I ran a quick regression (weighted by number of articles in each journal) using De Bruin’s awareness-adjusted quality score. This score is derived from a survey in which philosophers rated journals for quality and reported how familiar they were with them, which taken together should yield a reasonable proxy for prominence.<br />
The models suggest that there is a weak relationship. We explain only about 12% of the variance (and therefore would fare very badly trying to predict alphabetization rates from journal rank alone). But higher-ranked journals still show measurably more intentional alphabetization \(r(36)=.34,\,p=.036,\,R^{2}=.12\).  The model predicts 25 percentage points more intentional alphabetization in the top-rated journals than in the lowest-rated ones.</p>

<div class="row mt-3 justify-content-center">
  <div class="col-12">


<figure>
  <picture>
    <!-- Auto scaling with imagemagick -->
    <!--
      See https://www.debugbear.com/blog/responsive-images#w-descriptors-and-the-sizes-attribute and
      https://developer.mozilla.org/en-US/docs/Learn/HTML/Multimedia_and_embedding/Responsive_images for info on defining 'sizes' for responsive images
    -->
    
      <source class="responsive-img-srcset" srcset="/published/releases/37759233288-1/assets/img/authorship_order_philosophy/alphabetical_order_vs_quality-480.webp 480w,/published/releases/37759233288-1/assets/img/authorship_order_philosophy/alphabetical_order_vs_quality-800.webp 800w,/published/releases/37759233288-1/assets/img/authorship_order_philosophy/alphabetical_order_vs_quality-1400.webp 1400w," sizes="95vw" type="image/webp" />
    
    <img src="/published/releases/37759233288-1/assets/img/authorship_order_philosophy/alphabetical_order_vs_quality.png" width="100%" height="auto" loading="eager" onerror="this.onerror=null; $('.responsive-img-srcset').remove();" />
  </picture>

  
    <figcaption class="caption">Figure 5.  Journal-prestige as a (bad) predictor of intentional alphabetization rate.</figcaption>
  
</figure>

  </div>
</div>

<p><br /></p>

<p>Why? One thought is that top Anglophone journals tilt toward formal work and so quietly import authorship norms from formal disciplines. Another is that authorship-order disputes are less lenient in high-impact venues; collaborators may therefore converge on external, low-friction conventions.</p>

<h2 id="final-thoughts">Final thoughts</h2>

<p>So, where does that leave us? We have seen, contemporary philosophy lacks a strong, field-wide convention of alphabetical ordering, and the limited practice that does exist appears to be disappearing in recent years. Alphabetization is somewhat more common in formal, high-impact venues, yet even there intentional alphabetical ordering reaches only about 40–60 percent. Casual readers, therefore, cannot be expected to infer that an alphabetical byline reflects a deliberate choice rather than some other dynamic, especially if they usually read work from throughout the discipline. In the most formal subfields, alphabetization may work well as a choice, because the conventions are comparatively robust. By contrast, in areas such as history and philosophy of science, or in applied ethics, it seems unlikely that it is reliably interpreted.</p>

<p><em>Note on the use of generative AI: a lot of the code for this analysis was produced using OpenAI’s o3 model. The text of this blog post was dictated to MacWhisper and edited afterwards. Depending on your general view of my work, you may adjust your estimate of the results’ quality upward or downward accordingly.</em></p>]]></content><author><name></name></author><category term="philosophy" /><category term="authorship" /><category term="bibliometrics" /><summary type="html"><![CDATA[Philosophers don't often co-author. But if they do...?]]></summary></entry><entry><title type="html">Philosophical Easter Eggs</title><link href="https://maxnoichl.eu/blog/2025/easter-eggs/" rel="alternate" type="text/html" title="Philosophical Easter Eggs" /><published>2025-04-16T12:00:00+00:00</published><updated>2025-04-16T12:00:00+00:00</updated><id>https://maxnoichl.eu/blog/2025/easter%20eggs</id><content type="html" xml:base="https://maxnoichl.eu/blog/2025/easter-eggs/"><![CDATA[<p>For a research project, I had recently had occasion to extract the examples, thought-experiments, metaphors, from some twenty-thousand philosophical texts. As it’s Easter, I looked up the word ‘egg’ in the examples. Below I’ve collected some of my favourites among these quotes. I’ve illustrated them with an image generating model trained on works from the Rijksmuseum and a collection of hand-curated AI-weirdness. There’s no context to these quotes, theres no purpose to this exercise, I just think they’re neat.</p>

<blockquote>
  <p><em>Whether or not to count 1/8 th of an ostrich egg as equivalent to one chicken egg (for the purpose of making ‘One-Bowl Brownies’) is not implicit in the instruction ‘add three eggs’.</em></p>
</blockquote>

<div class="row mt-3 justify-content-center">
  <div class="col-12">


<figure>
  <picture>
    <!-- Auto scaling with imagemagick -->
    <!--
      See https://www.debugbear.com/blog/responsive-images#w-descriptors-and-the-sizes-attribute and
      https://developer.mozilla.org/en-US/docs/Learn/HTML/Multimedia_and_embedding/Responsive_images for info on defining 'sizes' for responsive images
    -->
    
    <img src="/published/releases/37759233288-1/assets/img/easter_eggs/brownie.webp" class="img-fluid rounded z-depth-1" width="100%" height="auto" loading="eager" onerror="this.onerror=null; $('.responsive-img-srcset').remove();" />
  </picture>

  
</figure>

  </div>
</div>

<p><br /></p>
<div style="text-align: center;">
<span class="ornamental">-.-</span>
</div>

<blockquote>
  <p><em>A cabbit is allegedly the product of crossbreeding. (I say allegedly because some have claimed the cabbit is, in fact, a physically altered Manx cat.) Take a rabbit ovum, fertilize it in vitro with feline sperm, and implant the fertilized egg in a fecund female rabbit and, with a little patience and far too much federal grant money, one is able to produce a cabbit. “I do not know why you would want one,” writes Stout, for the cabbit is a rather disturbing creature. Featuring the hindquarters of a rabbit, replete with hopping legs and bushy tail, and the head of a cat, the cabbit is what can only be called an “abomination.”</em></p>
</blockquote>

<div class="row mt-3 justify-content-center">
  <div class="col-12">


<figure>
  <picture>
    <!-- Auto scaling with imagemagick -->
    <!--
      See https://www.debugbear.com/blog/responsive-images#w-descriptors-and-the-sizes-attribute and
      https://developer.mozilla.org/en-US/docs/Learn/HTML/Multimedia_and_embedding/Responsive_images for info on defining 'sizes' for responsive images
    -->
    
    <img src="/published/releases/37759233288-1/assets/img/easter_eggs/cabbit.webp" class="img-fluid rounded z-depth-1" width="100%" height="auto" loading="eager" onerror="this.onerror=null; $('.responsive-img-srcset').remove();" />
  </picture>

  
</figure>

  </div>
</div>

<p><br /></p>
<div style="text-align: center;">
<span class="ornamental">-.-</span>
</div>
<p><br /></p>

<blockquote>
  <p><em>Who murdered Eggs Benedict? Was it Beef Strogonoff? Was it Chicken Cacciatore? Where was Eggs Benedict murdered? Was it in the Bronx? When? At 2:00 A. M. January 24, 1963? Why? Did he squeal? How? With this knife?</em></p>
</blockquote>

<div class="row mt-3 justify-content-center">
  <div class="col-12">


<figure>
  <picture>
    <!-- Auto scaling with imagemagick -->
    <!--
      See https://www.debugbear.com/blog/responsive-images#w-descriptors-and-the-sizes-attribute and
      https://developer.mozilla.org/en-US/docs/Learn/HTML/Multimedia_and_embedding/Responsive_images for info on defining 'sizes' for responsive images
    -->
    
    <img src="/published/releases/37759233288-1/assets/img/easter_eggs/benedict.webp" class="img-fluid rounded z-depth-1" width="100%" height="auto" loading="eager" onerror="this.onerror=null; $('.responsive-img-srcset').remove();" />
  </picture>

  
</figure>

  </div>
</div>

<p><br /></p>
<div style="text-align: center;">
<span class="ornamental">-.-</span>
</div>

<blockquote>
  <p><em>Let us take the case of an animal which has all the regular characteristics of a cat except that it alternately gives birth to kittens and lays eggs. Shall we still call this animal a cat?</em></p>
</blockquote>

<div class="row mt-3 justify-content-center">
  <div class="col-12">


<figure>
  <picture>
    <!-- Auto scaling with imagemagick -->
    <!--
      See https://www.debugbear.com/blog/responsive-images#w-descriptors-and-the-sizes-attribute and
      https://developer.mozilla.org/en-US/docs/Learn/HTML/Multimedia_and_embedding/Responsive_images for info on defining 'sizes' for responsive images
    -->
    
    <img src="/published/releases/37759233288-1/assets/img/easter_eggs/cat_egg.webp" class="img-fluid rounded z-depth-1" width="100%" height="auto" loading="eager" onerror="this.onerror=null; $('.responsive-img-srcset').remove();" />
  </picture>

  
</figure>

  </div>
</div>

<p><br /></p>
<div style="text-align: center;">
<span class="ornamental">-.-</span>
</div>

<blockquote>
  <p><em>For instance, it may very well happen that certain individuals, e.g. certain stones or leaves, turn out to be both reddish and greenish, while others, e.g. sand dunes or egg yolks, are not classified at all. In that case, it is recommended that two things be done: (1) introducing a new colour predicate ‘ yellow ‘ by ostensive definition, say with ripe lemons and dunes as paradigms, and (2) extending and stabilizing (1) by setting up the rule ‘ reddish, greenish =&gt; yellow’ (if reddish as well as greenish hold of something, yellow, too, shall hold of that same thing).</em></p>
</blockquote>

<div class="row mt-3 justify-content-center">
  <div class="col-12">


<figure>
  <picture>
    <!-- Auto scaling with imagemagick -->
    <!--
      See https://www.debugbear.com/blog/responsive-images#w-descriptors-and-the-sizes-attribute and
      https://developer.mozilla.org/en-US/docs/Learn/HTML/Multimedia_and_embedding/Responsive_images for info on defining 'sizes' for responsive images
    -->
    
    <img src="/published/releases/37759233288-1/assets/img/easter_eggs/color.webp" class="img-fluid rounded z-depth-1" width="100%" height="auto" loading="eager" onerror="this.onerror=null; $('.responsive-img-srcset').remove();" />
  </picture>

  
</figure>

  </div>
</div>

<p><br /></p>
<div style="text-align: center;">
<span class="ornamental">-.-</span>
</div>

<blockquote>
  <p><em>A drawing of an egg would, if reference to Lord Snow were established, be a perfectly legitimate caricature of him.</em></p>
</blockquote>

<div class="row mt-3 justify-content-center">
  <div class="col-12">


<figure>
  <picture>
    <!-- Auto scaling with imagemagick -->
    <!--
      See https://www.debugbear.com/blog/responsive-images#w-descriptors-and-the-sizes-attribute and
      https://developer.mozilla.org/en-US/docs/Learn/HTML/Multimedia_and_embedding/Responsive_images for info on defining 'sizes' for responsive images
    -->
    
    <img src="/published/releases/37759233288-1/assets/img/easter_eggs/portrait.webp" class="img-fluid rounded z-depth-1" width="100%" height="auto" loading="eager" onerror="this.onerror=null; $('.responsive-img-srcset').remove();" />
  </picture>

  
</figure>

  </div>
</div>

<p><br /></p>
<div style="text-align: center;">
<span class="ornamental">-.-</span>
</div>

<blockquote>
  <p><em>The universe e.g. was made out of the cosmic egg, floating in the primeval waters-another symbol of fertility and probably even sexual energy; or it was begotten by an ancestral couple, usually heaven and earth.</em></p>
</blockquote>

<div class="row mt-3">
  <div class="col-12">


<figure>
  <picture>
    <!-- Auto scaling with imagemagick -->
    <!--
      See https://www.debugbear.com/blog/responsive-images#w-descriptors-and-the-sizes-attribute and
      https://developer.mozilla.org/en-US/docs/Learn/HTML/Multimedia_and_embedding/Responsive_images for info on defining 'sizes' for responsive images
    -->
    
    <img src="/published/releases/37759233288-1/assets/img/easter_eggs/heavenly.webp" class="img-fluid rounded z-depth-1" width="100%" height="auto" loading="eager" onerror="this.onerror=null; $('.responsive-img-srcset').remove();" />
  </picture>

  
</figure>

  </div>
</div>

<p><br /></p>
<div style="text-align: center;">
<span class="ornamental">-.-</span>
</div>

<blockquote>
  <p><em>(a) Upon observing a single platypus (I’ll call her Paula) lay eggs, we infer that all (female) platypuses lay eggs.</em></p>
</blockquote>

<div class="row mt-3 justify-content-center">
  <div class="col-12">


<figure>
  <picture>
    <!-- Auto scaling with imagemagick -->
    <!--
      See https://www.debugbear.com/blog/responsive-images#w-descriptors-and-the-sizes-attribute and
      https://developer.mozilla.org/en-US/docs/Learn/HTML/Multimedia_and_embedding/Responsive_images for info on defining 'sizes' for responsive images
    -->
    
    <img src="/published/releases/37759233288-1/assets/img/easter_eggs/paula.webp" class="img-fluid rounded z-depth-1" width="100%" height="auto" loading="eager" onerror="this.onerror=null; $('.responsive-img-srcset').remove();" />
  </picture>

  
</figure>

  </div>
</div>

<p><br /></p>
<div style="text-align: center;">
<span class="ornamental">-.-</span>
</div>

<blockquote>
  <p><em>In other words, our is chickens are necessarily informed by ought eggs.</em></p>
</blockquote>

<div class="row mt-3 justify-content-center">
  <div class="col-12">


<figure>
  <picture>
    <!-- Auto scaling with imagemagick -->
    <!--
      See https://www.debugbear.com/blog/responsive-images#w-descriptors-and-the-sizes-attribute and
      https://developer.mozilla.org/en-US/docs/Learn/HTML/Multimedia_and_embedding/Responsive_images for info on defining 'sizes' for responsive images
    -->
    
    <img src="/published/releases/37759233288-1/assets/img/easter_eggs/is_ought_chicken.webp" class="img-fluid rounded z-depth-1" width="100%" height="auto" loading="eager" onerror="this.onerror=null; $('.responsive-img-srcset').remove();" />
  </picture>

  
</figure>

  </div>
</div>

<p><br /></p>
<div style="text-align: center;">
<span class="ornamental">-.-</span>
</div>]]></content><author><name></name></author><category term="nonsense" /><category term="eggs" /><category term="philosophy" /><category term="ai" /><summary type="html"><![CDATA[Some eggsamples from the recent philosophical literature.]]></summary></entry></feed>